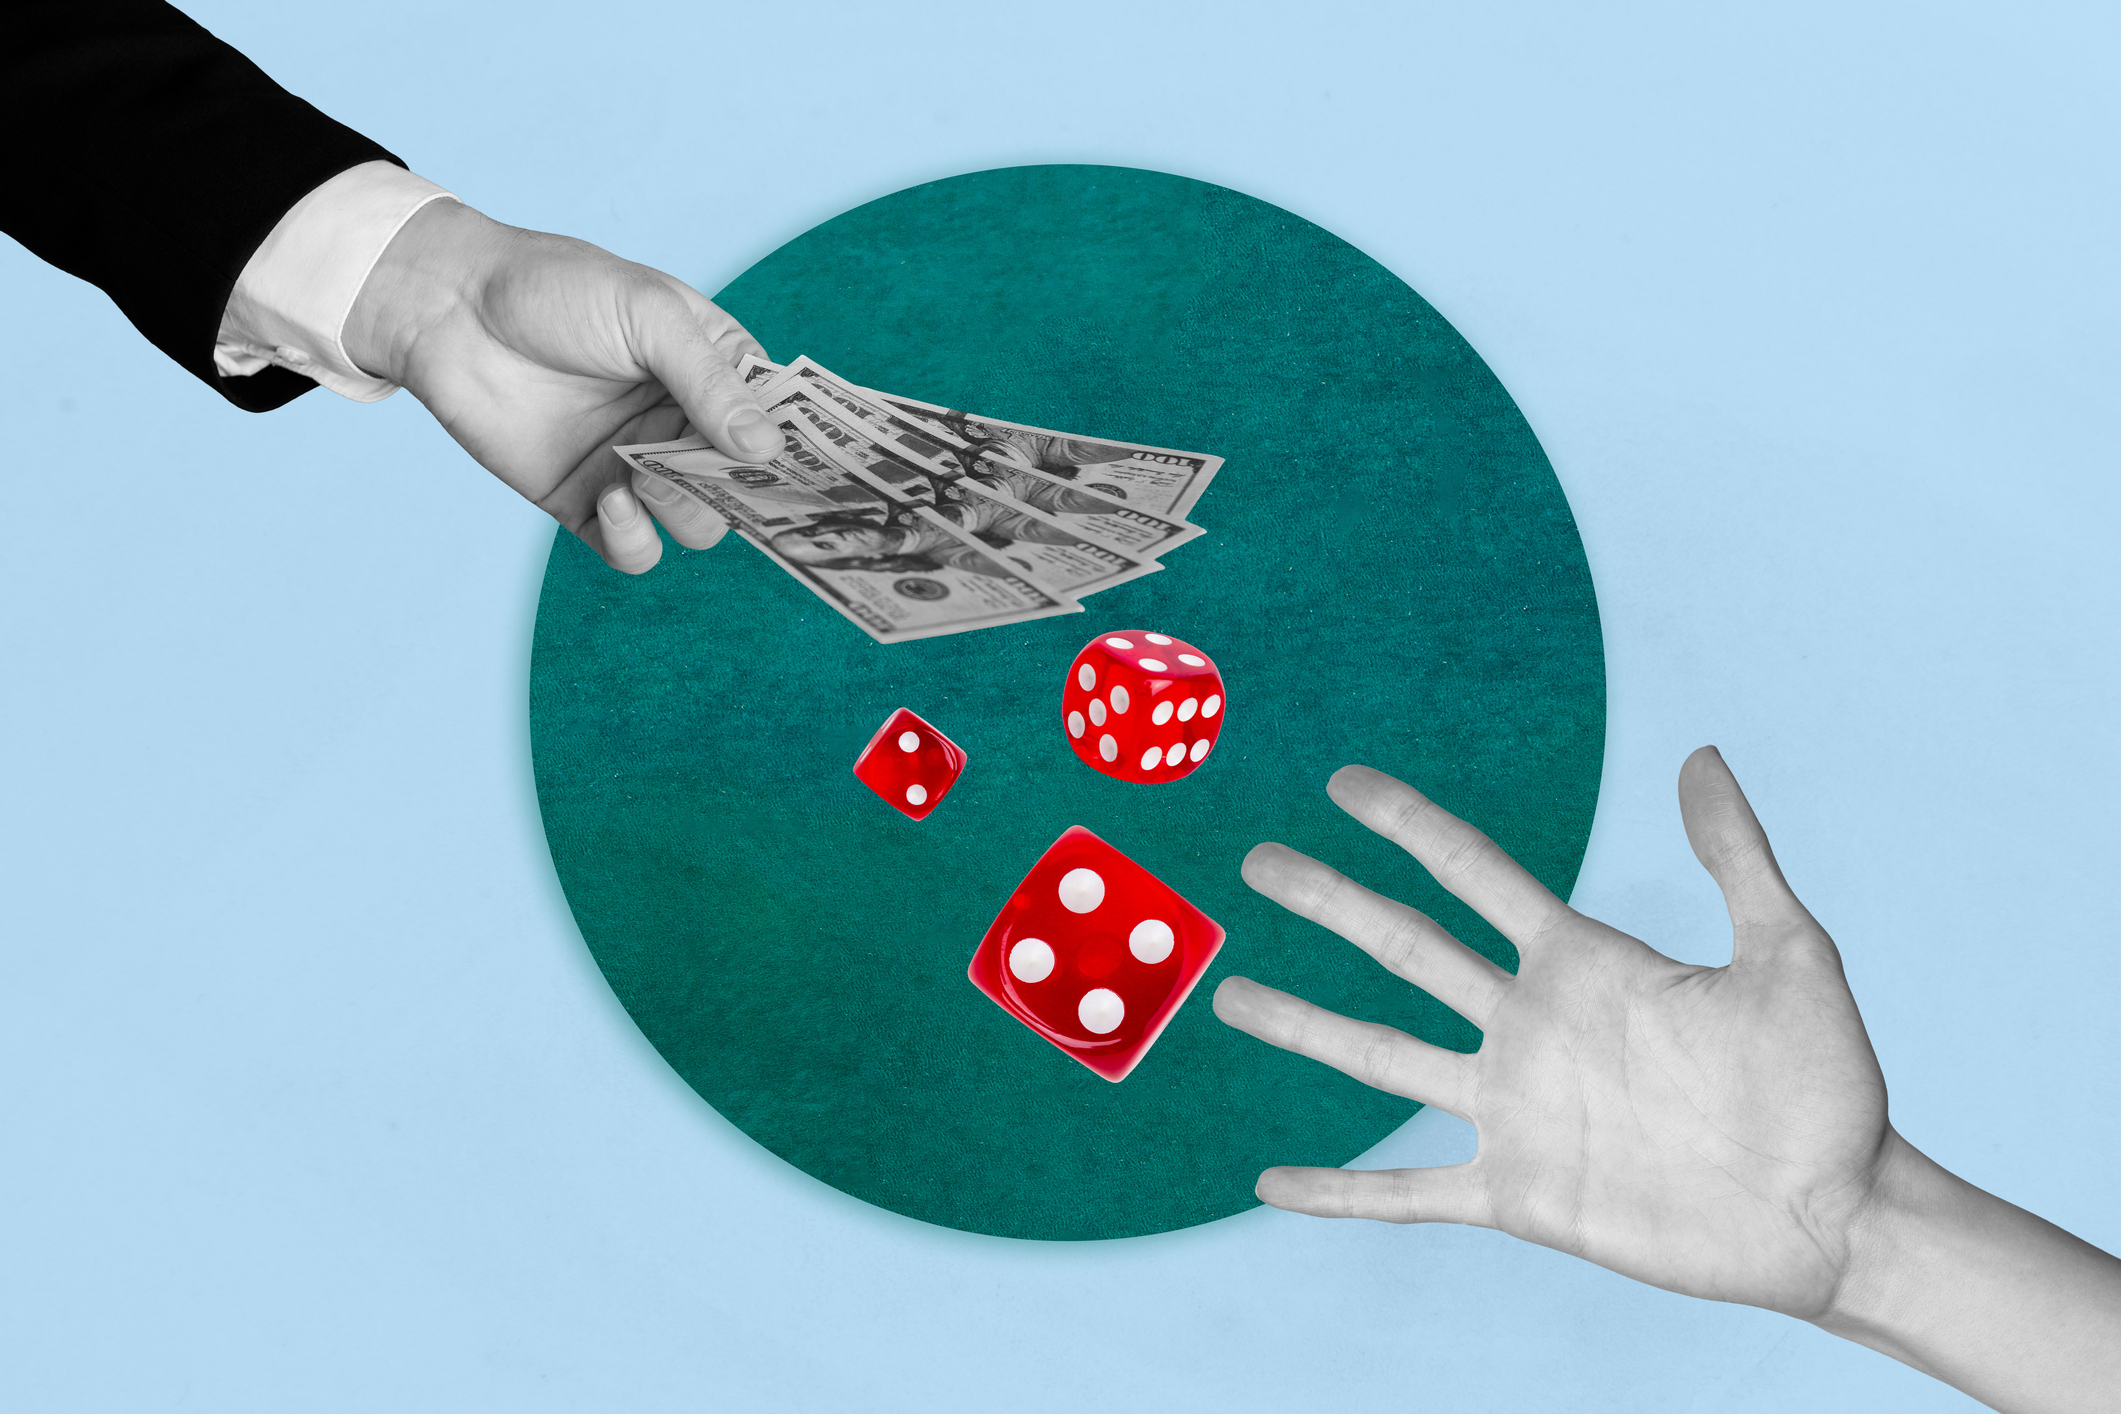
Every tech boom has a moment when possibility starts moving faster than proof.
We saw it with the internet, social media, programmatic advertising, big data, and every other technology that arrived with the promise that business would never work the same way again. Some of those promises were right, while many were wildly overstated. But all of them took years to sort out.
AI may be different in scale, but the psychology around it is familiar. Right now, nobody wants to be the company that moves too slowly. Boards are asking what AI can replace as teams are pushed to do more with less, while vendors race to show what their models can simulate, automate, and predict. In market research, one of the most seductive promises is that we may no longer need to ask quite so many people what they think.
Why wait weeks for a survey, a focus group, or a series of interviews if a synthetic audience can give you an answer in minutes? It is an entirely reasonable question, until the answer is being used to decide where a brand puts its money.
Would you bet the brand on it?
There is a significant difference between an AI model saying consumers are likely to respond well to a campaign and 1,000 consumers actually telling you that they do. A synthetic audience may predict that a new product will resonate, while real people may question the proposition, misunderstand it, reject it, or respond in ways nobody anticipated.
None of that makes synthetic data useless. Its value may lie in helping brands form an opinion before they spend the time and money required to test it properly, by surfacing possibilities, challenging assumptions, and narrowing the field of ideas worth investigating.
The real dividing line is between “this might be true” and “this is true strongly enough that we should act on it.” Synthetic data may help brands decide what they think; market research still has to determine whether real people agree strongly enough to justify the decision.
“The survey said” still means something
For all its flaws, traditional market research has one advantage that is easy to overlook in the rush toward synthetic data: there is a real person behind the answer.
People misremember, exaggerate, and misunderstand questions, while poorly designed surveys, dominant focus-group voices, and weak interviewing can all distort the result. Researchers know this because the industry has spent decades studying where human research goes wrong and how to account for it.
Sampling error, recruitment bias, questionnaire effects, interviewer influence, and the gap between stated intention and actual behavior are not theoretical weaknesses. They are known limitations, with established ways to assess and communicate them.
When a brand hears that 62% of consumers prefer one proposition over another, there is a chain of evidence behind that number. People were recruited, shown something, asked a question, and gave an answer. We can debate whether the sample was representative, whether the question was fair, or whether those consumers will behave the same way in the real world, but we know where the finding came from.
Synthetic data breaks that chain. A model can tell us that consumers are likely to prefer proposition A, that one audience may respond better than another, or that a particular message is likely to resonate, and the output may look almost identical to conventional research.
But no consumer necessarily saw the proposition or made the choice. The response is a modeled prediction of what people might say, not a record of what they actually did say.
Once both are turned into a chart and placed on a slide, “the research says” and “the model says” can sound dangerously similar.
Plausible is not the same as proven
One reason synthetic data is so easy to trust is that it looks familiar. The outputs arrive in forms researchers already know how to read: preference scores, segment differences, reasons for choosing one concept over another, sometimes even open-ended language that sounds entirely human.
The problem is that a plausible answer can still be wrong in ways that matter commercially.
A synthetic respondent does not have to say anything obviously absurd to lead you in the wrong direction. The greater risk may be when the answer sounds perfectly reasonable, because reasonable is often exactly what the model has learned to produce.
Research earns its value when it reveals something the business did not already know. The campaign everyone loved internally may fall flat, the feature considered central to the proposition may barely register with customers, while an audience nobody expected to lead may respond most strongly.
Those surprises are often where the commercial value sits. A synthetic system may be very good at identifying what is likely, typical, or culturally familiar, but research is often most useful when reality does not behave as expected.
We are already seeing signs of that problem in the evidence. A 2024 study in Political Analysis found that synthetic ChatGPT responses could look remarkably similar to human survey results at the aggregate level, while the underlying relationships told a different story. Almost half of the regression coefficients differed significantly from the human data, and among those differences, the direction of the effect reversed nearly a third of the time.
For researchers, that is the real problem. The headline result can look close enough to reassure you, while the story underneath it points somewhere else entirely.
So what should brands actually do with that? If a synthetic audience suggests one campaign territory is stronger than another, that may be enough to justify further investigation, and if two product ideas appear more promising than the rest, it may help a team decide where to concentrate its research budget.
But once the question is whether to launch, invest, reposition, or walk away, plausibility is no longer enough. The test becomes whether real people would lead you to the same decision.
The test synthetic data now needs to pass
The next step is not another demonstration of how convincingly synthetic respondents can mimic human ones. It is a proper test of whether they lead researchers and brands to the same decisions.
Run the synthetic study first, lock the results, then run the human study independently. Compare the concept rankings, segment differences, purchase intent, and the reasons behind the responses, but do not stop there. Compare the recommendations each study would have produced.
Would both approaches have told the brand to back the same campaign, launch the same product, target the same audience, or walk away from the same idea?
We already have examples of why this matters. A 2026 benchmark using human data from the US General Social Survey and the World Values Survey found that synthetic models exaggerated differences between demographic segments by two to four times. When those differences were used to make a targeting decision, the synthetic results would have pointed to the wrong segment in half of the US cases and in most of the cross-cultural cases tested. The study is still a preprint, but the implication is difficult to ignore: a result can look analytically convincing and still send the business in the wrong direction.
At the same time, some synthetic approaches appear to perform far better than others. In a 2026 replication study, Qualtrics reported that its research-specific model tracked a matched human panel much more closely than general-purpose LLMs across eight attitudinal questions. It is vendor-produced evidence and should be treated as such, but it reinforces a point the industry will have to get comfortable with: “Does synthetic data work?” is probably the wrong question.
The better question is which synthetic method works, with which populations, for which kinds of problems, and how much validation is enough before anyone acts on the result.
The industry has spent a great deal of energy asking whether synthetic respondents can mimic human responses, when the more useful test is whether they reproduce the findings that actually change what a brand does.
Market research exists to reduce uncertainty around decisions with money attached, which means the benchmark for synthetic data cannot simply be whether it looks human. It has to be whether it leads brands to make the right call.
We need a new language for uncertainty
If synthetic data is going to become part of mainstream research, the industry needs a credible way to express uncertainty around it.
Conventional survey research already has one. We talk about sample size, confidence levels, margin of error, weighting, design effects, and the limitations of the sample, all of which help researchers explain how much confidence to place in a finding.
Synthetic data does not fit neatly into that system. If I generate 1,000 synthetic respondents and 62% prefer Concept A, what does 62% actually mean? If I generate 10,000, I have more responses, but do I have more evidence?
A traditional margin of sampling error exists because a sample has been drawn from a population. Synthetic respondents are generated by a model, so increasing the number of outputs may tell us more about variation within that model, but not how far the model itself sits from reality.
The standards are beginning to move in that direction. AAPOR now distinguishes AI-generated responses from those of human research participants and requires researchers to disclose how synthetic samples were created, as well as any human oversight or validation involved. That is useful progress, but transparency only tells us what produced the finding. It does not tell us how much confidence to place in it.
The next step is harder: researchers need to measure how far synthetic findings drift from human ones. That means benchmarking them repeatedly against real studies and identifying where gaps appear — in concept winners, distributions, audience differences, cultural contexts, or specific categories. Just as importantly, we need to know whether those gaps are stable or whether they shift when the model, population, or task changes.
I suspect research reports will start to look different as synthetic data becomes more common, because confidence in the result will need to be demonstrated rather than implied. Researchers may end up reporting how closely a method has tracked human benchmarks, how stable its findings are across models or populations, and how often it would have led to the same commercial decision as a human study.
That shifts the researcher’s role from choosing between “synthetic” and “human” to judging where each is credible, where it is vulnerable, and what level of evidence is required before a business should act.
We already know how to put a margin of error beside a survey statistic. The next challenge is to build an equally credible way to express uncertainty around a synthetic one.
Until then, “62% of synthetic consumers prefer Concept A” may look like a research finding, but every decision-maker should still ask the same question:
How much should I trust it?
How confident are you in the research behind your next big decision?
At Kadence, we believe the value of research lies in helping brands make better decisions, not simply producing convincing answers. Whether you're exploring new approaches or validating a major investment, we can help you find the evidence you need.
Talk to our research experts
FAQs
What is synthetic data in market research?
Synthetic data in market research refers to AI-generated responses designed to simulate how consumers might answer questions, evaluate products or react to marketing concepts. Unlike traditional research, these responses are produced by models rather than collected directly from human participants.
Can synthetic AI respondents replace real consumers in market research?
Not reliably across every research application. Synthetic respondents can help researchers explore hypotheses, identify potential patterns and prioritize ideas for further investigation. However, their ability to reproduce human responses varies by model, population and research task. Decisions involving significant commercial investment require appropriate validation.
How accurate is synthetic data compared with traditional market research?
Accuracy varies considerably. Research has found that synthetic responses can resemble human survey results at an aggregate level while misrepresenting underlying relationships or demographic differences. Some specialized models perform better than general-purpose AI systems, making independent benchmarking essential.
What are the biggest risks of using synthetic data for brand decisions?
The greatest risk is treating a plausible prediction as verified consumer evidence. Synthetic research may exaggerate audience differences, overlook unexpected reactions or suggest the wrong target segment. These errors can affect campaign development, product launches, positioning and investment decisions.
How should brands validate synthetic market research before making decisions?
Brands should benchmark synthetic findings against independently collected human research. This means comparing concept rankings, audience differences, purchase intent and, critically, the commercial recommendations each approach produces. Validation should also consider how consistently the method performs across populations, categories and research tasks.